Talk with our engineers by joining the new Onehouse community Slack!
THE OPEN DATABRICKS ALTERNATIVE
Open, faster, flexible lakehouse that runs anywhere
Same Apache Spark™, same SQL, on open tables.
Faster than Photon without the Photon tax, on any Kubernetes you already run.

How Onehouse stacks up
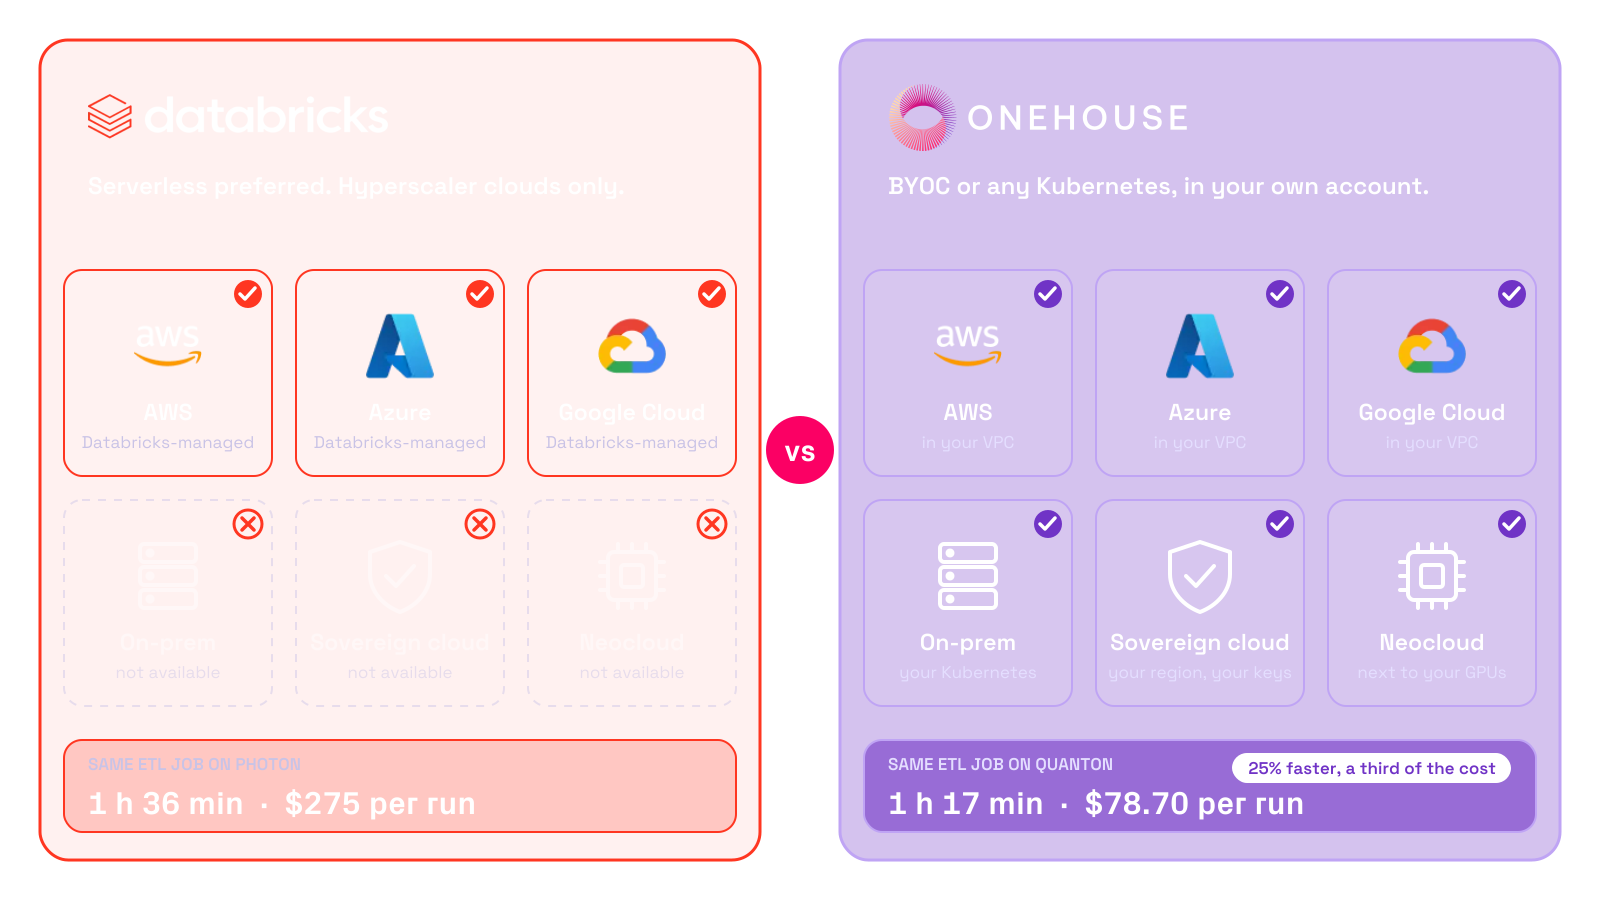
Shot for shot. Faster ingest, faster Spark, faster queries, on open tables any engine can read, in your own account with no DBUs.
| Capability | Databricks | Onehouse | How it is different |
|---|---|---|---|
| Streaming / ingest | Lakeflow | OneFlow | Lowest-latency CDC and streaming ingest at lakehouse scale. Writes to any catalog. No lock-in. |
| ETL & transformations | Photon, Lakeflow Spark Declarative Pipelines | Quanton SQL / Spark jobs | 25% faster than Photon at a third of the cost. 4x faster Apache Iceberg™ merges with index-aware joins. |
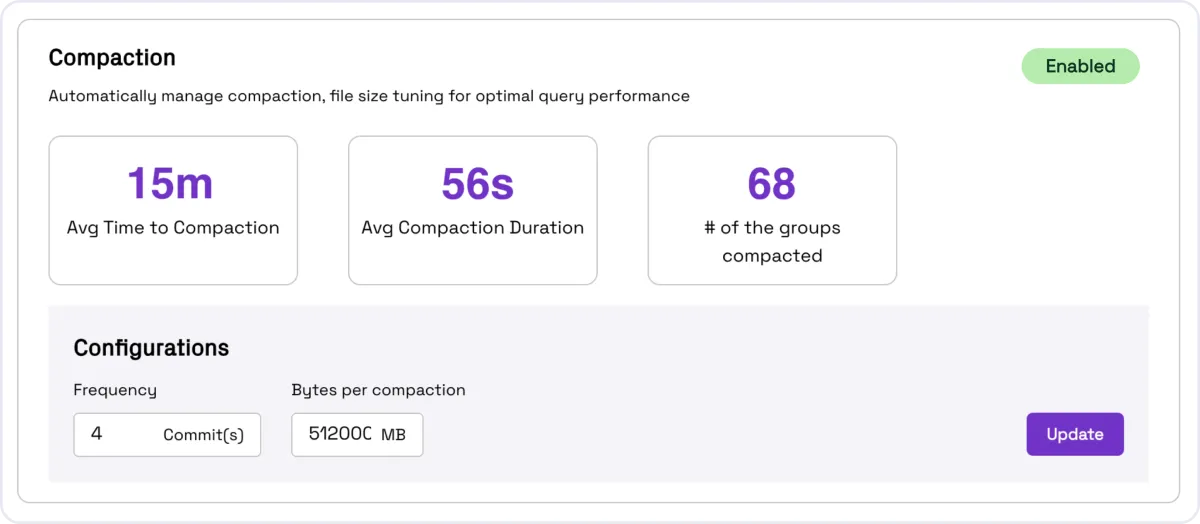
| Storage & table management | Unity Catalog managed tables, Predictive Optimization | Universal catalog, Table Optimizer | Compaction and clustering with 2–4x less compute. Any engine, any catalog reads and writes the tables. |
| Analytics / low-latency querying | SQL Warehouses, Databricks SQL Serverless | Lakegres, Open Engines | Sub-second Postgres endpoint on your lakehouse tables. 6x faster than SQL Serverless. |
| Agents & AI access | Unity AI Gateway, on Databricks compute only | AI Gateway + Lakegres | Model routing and MCP tools in your VPC, on-prem or neocloud. Traces land in open tables. |
| Deployment & cost | Serverless preferred; hyperscaler clouds only | BYOC or any Kubernetes, incl. on-prem and neocloud | Compute and data stay in your account. Your cloud discounts apply in full. |
| Spark on your own Kubernetes | Photon runs only on Databricks-managed compute | Quanton Kubernetes Operator (BYOK) | Drop-in for the Kubeflow Spark Operator, 4–6x faster than open-source Spark. Any cluster, any cloud, on-prem. |
Open. Faster. Flexible. Cheaper.

Open
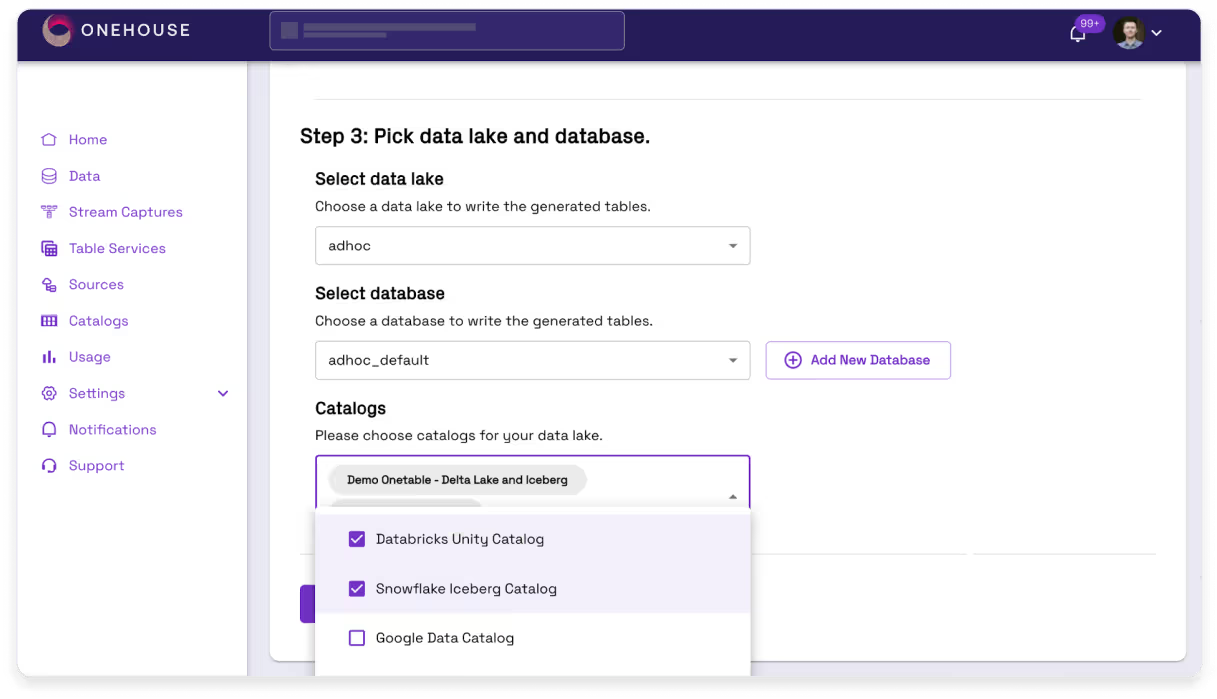
Apache Iceberg™, Delta Lake and Apache Hudi™ in your buckets, registered with Glue, Unity, Snowflake and Polaris. Databricks treats Iceberg it does not govern as read-only. Onehouse writes to all of them.

Faster
25% faster than Photon on production ETL, 6x faster than open-source Spark on TPC-DS, 4x faster Iceberg merges. Measured on TPC-DS and on a customer's own pipelines, not a demo.

Flexible
Any Kubernetes: EKS, GKE, AKS, OpenShift, on-prem, air-gapped, neocloud. Same spark-submit, no code changes, and leaving is one config line.

Cheaper
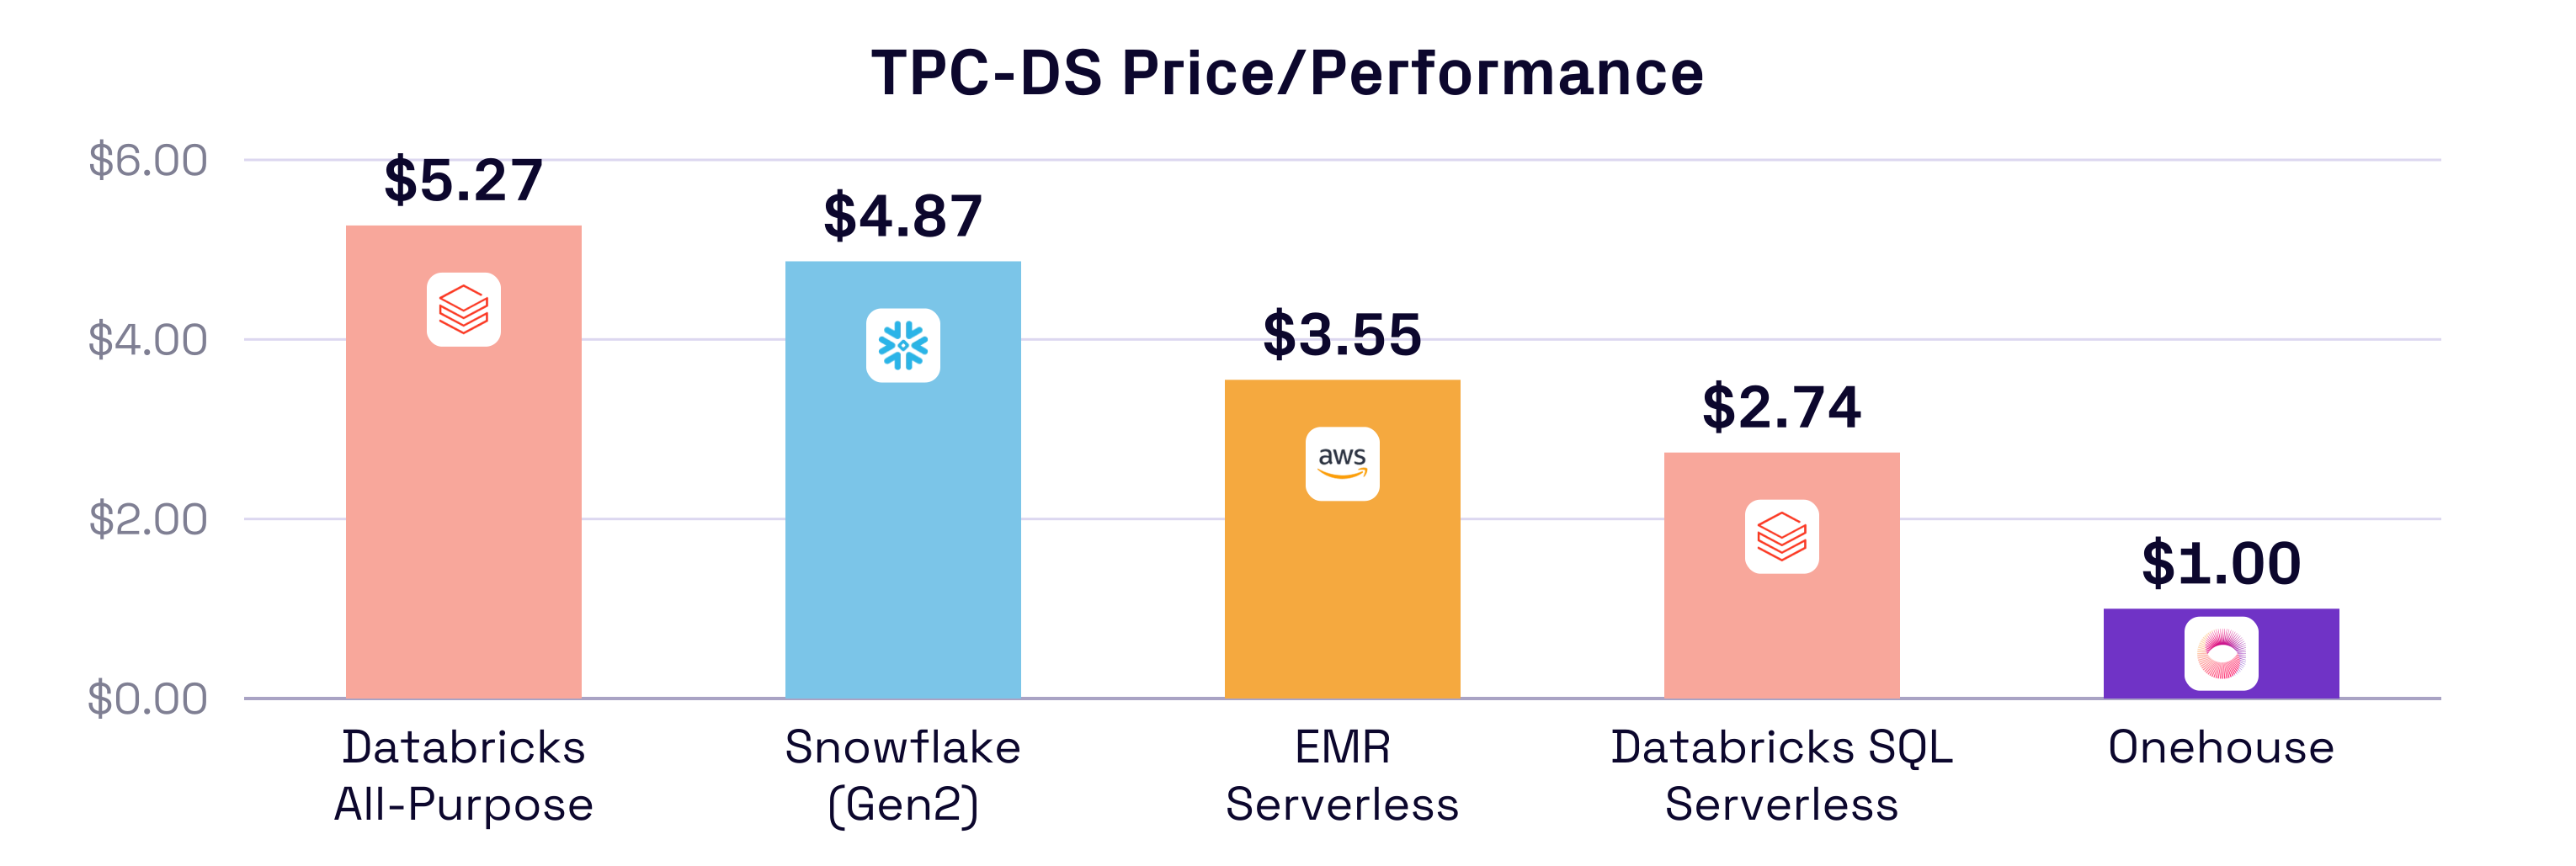
Pay for data processed, not DBUs. On TPC-DS the same work costs 5.3x more on Databricks All-Purpose compute and 2.7x more on SQL Serverless.
Streaming and CDC ingestion that stays open
Lakeflow lands data in Databricks' storage, catalog and engine. OneFlow lands Iceberg or Hudi tables in your buckets with record-level indexing and merge-on-read, and registers it with Glue, Unity, Snowflake and Polaris in one pass. In production that is 350+ TB a day of CDC on a single customer, with every engine reading the same tables.
Faster than Photon, without the Photon tax
Quanton runs real Apache Spark with no per-cluster premium and no code changes. The chart shows what that buys per dollar on TPC-DS.
4xfaster Iceberg merges, with index-aware joins and low-shuffle MERGE INTO
25%faster than Photon on a public fintech's production ETL, as well as TPC-DS 10 TB
2.9xthe DBUs Photon emits over standard Spark on the same instance. Quanton has no special tax.Table management that does not require Unity Catalog
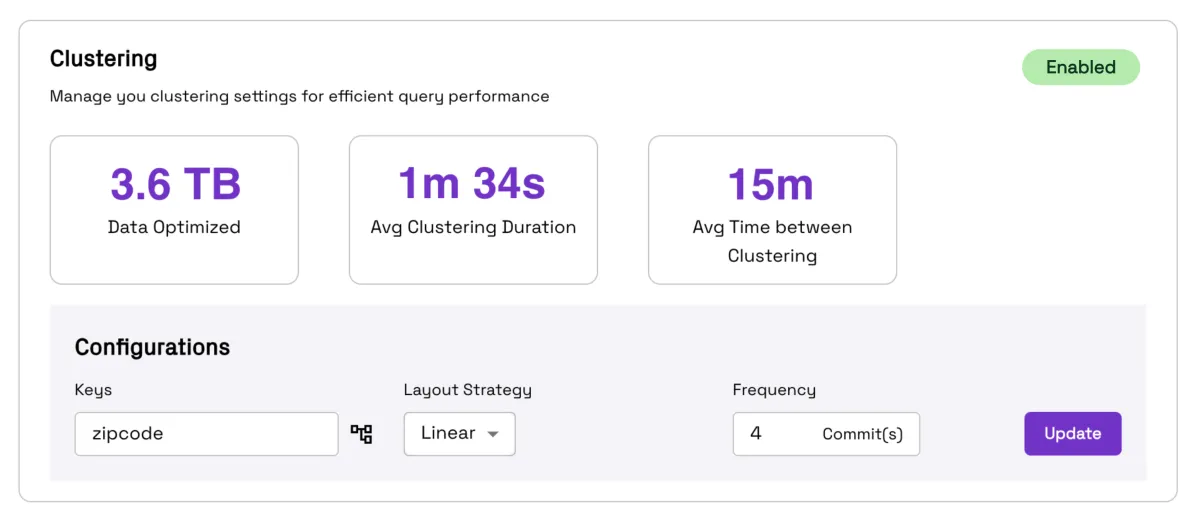
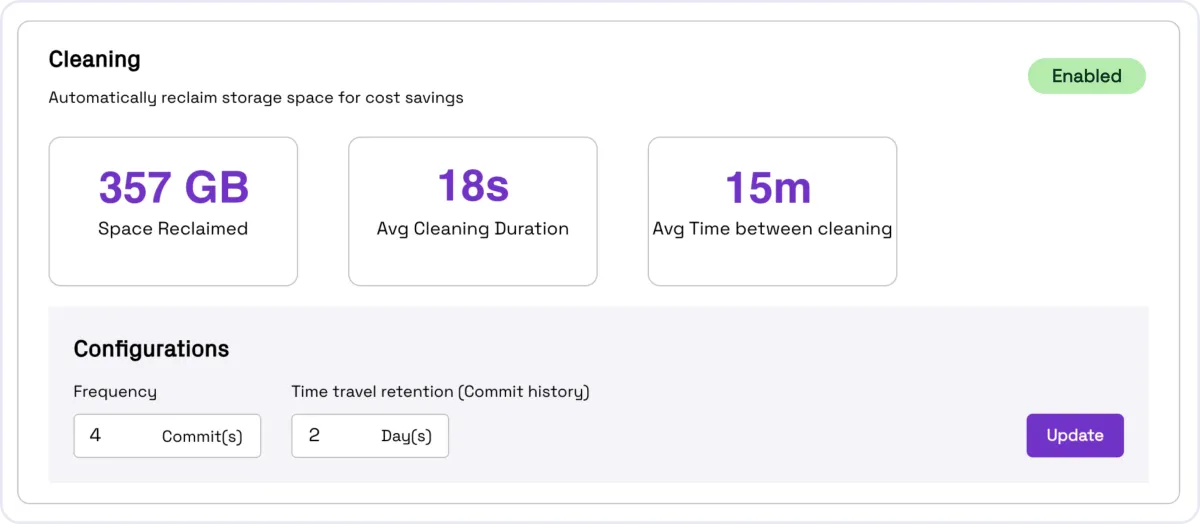
Databricks' own documentation makes Unity Catalog mandatory for Iceberg: any table governed by Glue, Polaris or Nessie is a "foreign Iceberg table", read-only, with no partition evolution and no branching. Table Optimizer runs incremental clustering, intelligent compaction and columnar compaction asynchronously with 2–4x less compute, on tables every engine and catalog can read and write. At a $700B+ pension fund it sped up Athena 1.7x, Spark 9x and Trino 12x on the same tables, without changing a query.
Database-speed queries directly on open Iceberg tables
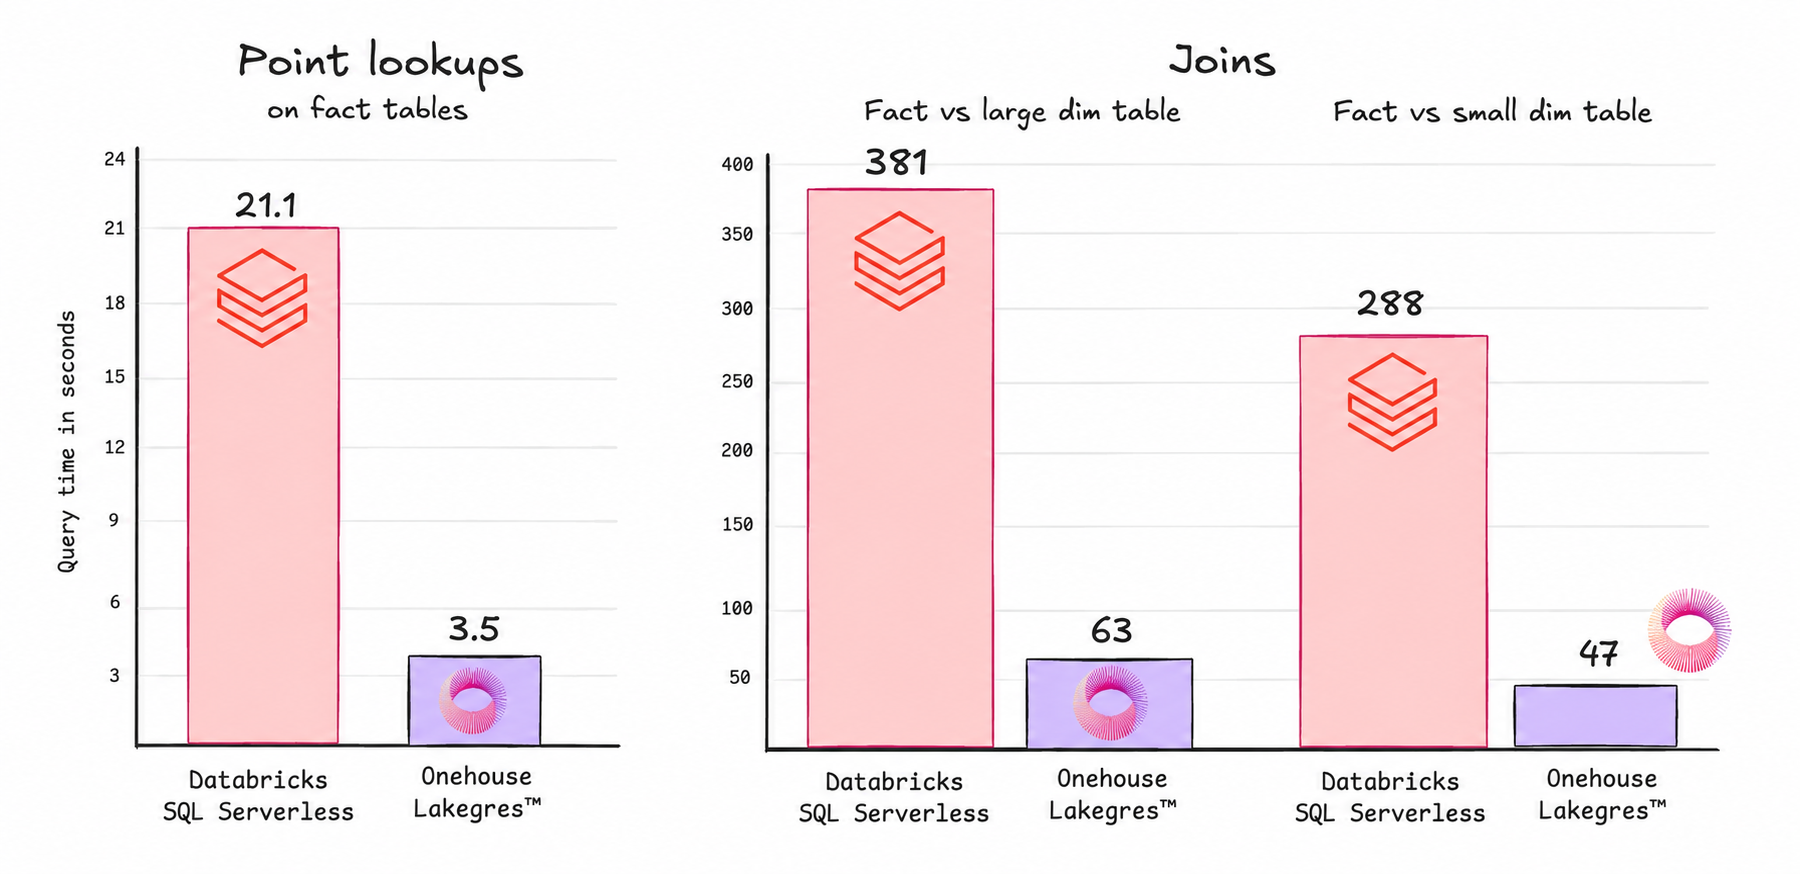
Lakegres serves your Iceberg and Hudi tables through a Postgres wire-compatible endpoint, with record-level indexes and columnar caching. Against Databricks SQL Serverless: point lookups 3.5s versus 21.1s, joins 63s versus 381s. Same tables, no copy into a warehouse.
The only lakehouse that will keep up with your AI agents
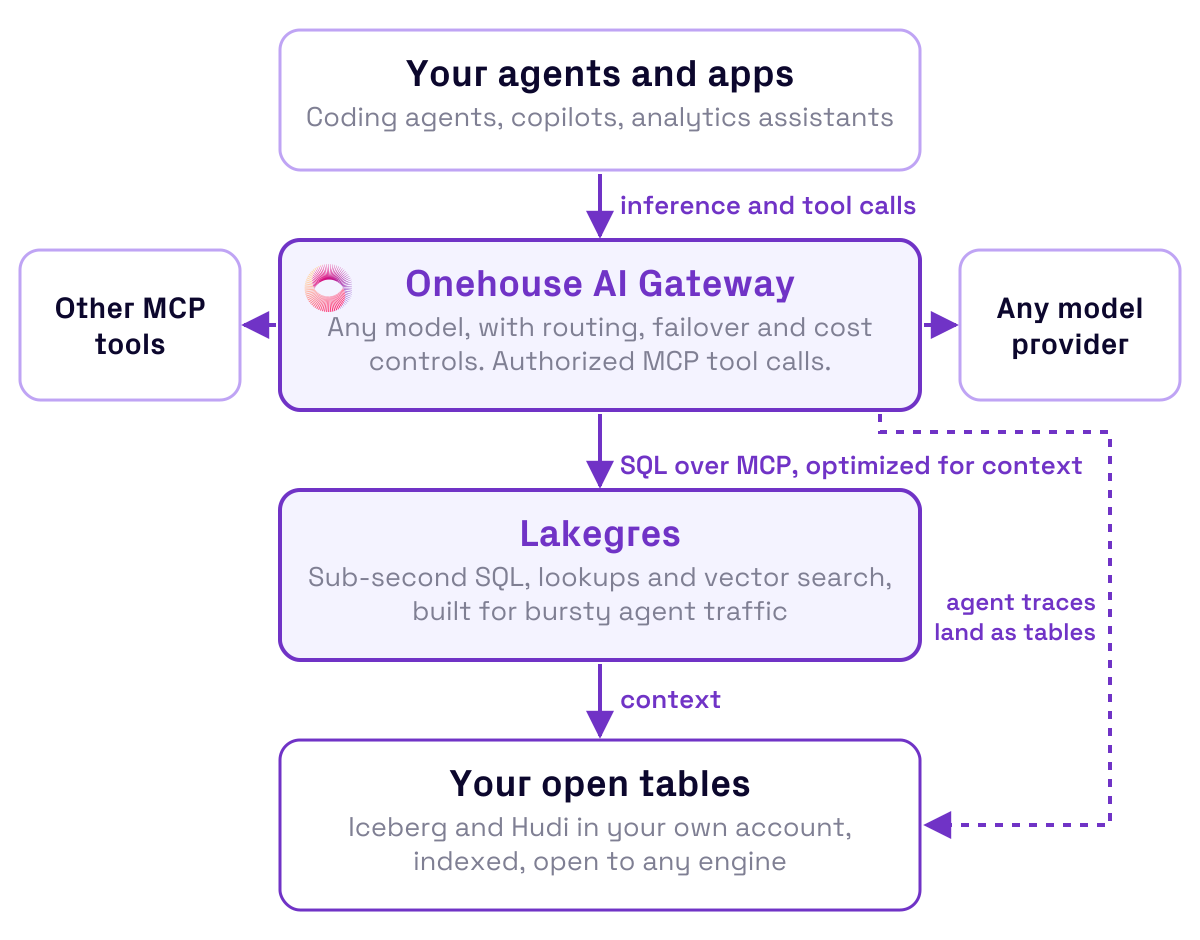
Agents think by querying: bursts of point lookups and scans at hundreds of QPS. Lakegres is built for that traffic, with sub-second SQL and vector search on your open tables. Onehouse AI Gateway routes any model from any provider with failover and cost controls, and its built-in MCP server optimizes context queries, so answers come back more accurate, faster and cheaper. Traces land as open tables. Unity AI Gateway runs only on Databricks compute and charges per GB to log them.
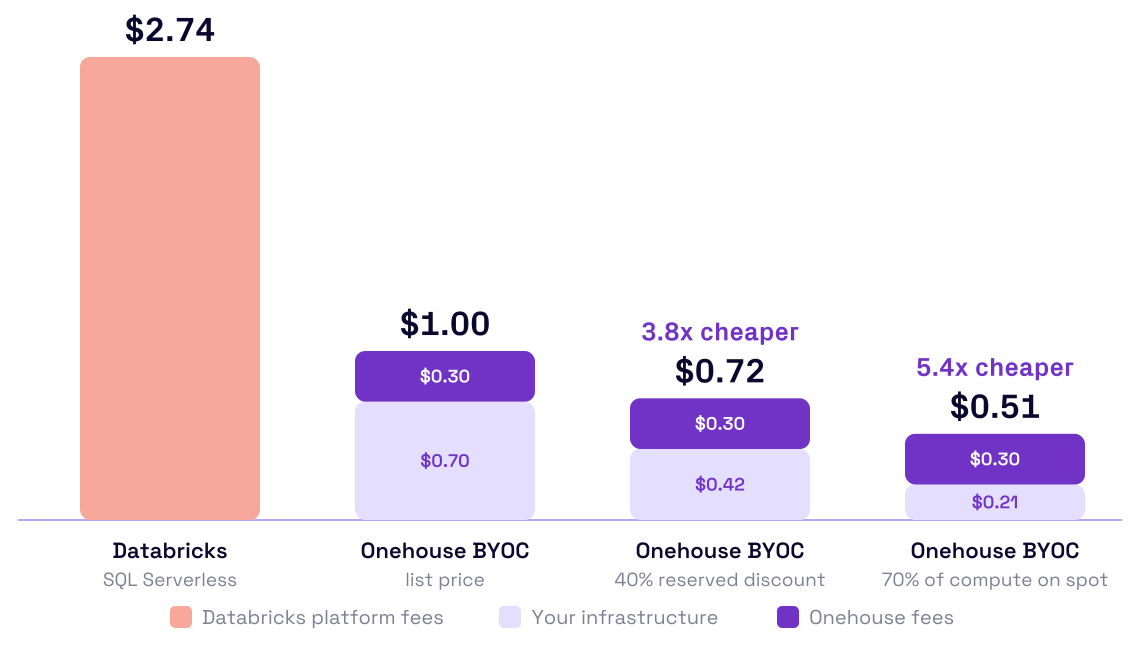
Same TPC-DS work, cost normalized to Onehouse at list price. Reserved and spot pricing cut the infrastructure share by 40 to 70%.
Your cloud, your discounts, or no cloud at all
Databricks runs on its own compute in the hyperscaler clouds, with serverless as the preferred path. Onehouse runs on a Kubernetes compute runtime in your account: virtual clusters with queues and resource isolation, your negotiated rates. Your reserved-instance and spot discounts apply to the infrastructure share, 70% of the bill at list price, so the same work lands 3.8 to 5.4x under Databricks SQL Serverless. The same runtime deploys on-prem, air-gapped, or on a neocloud next to your GPUs.
Keep your Kubernetes. Swap the operator.
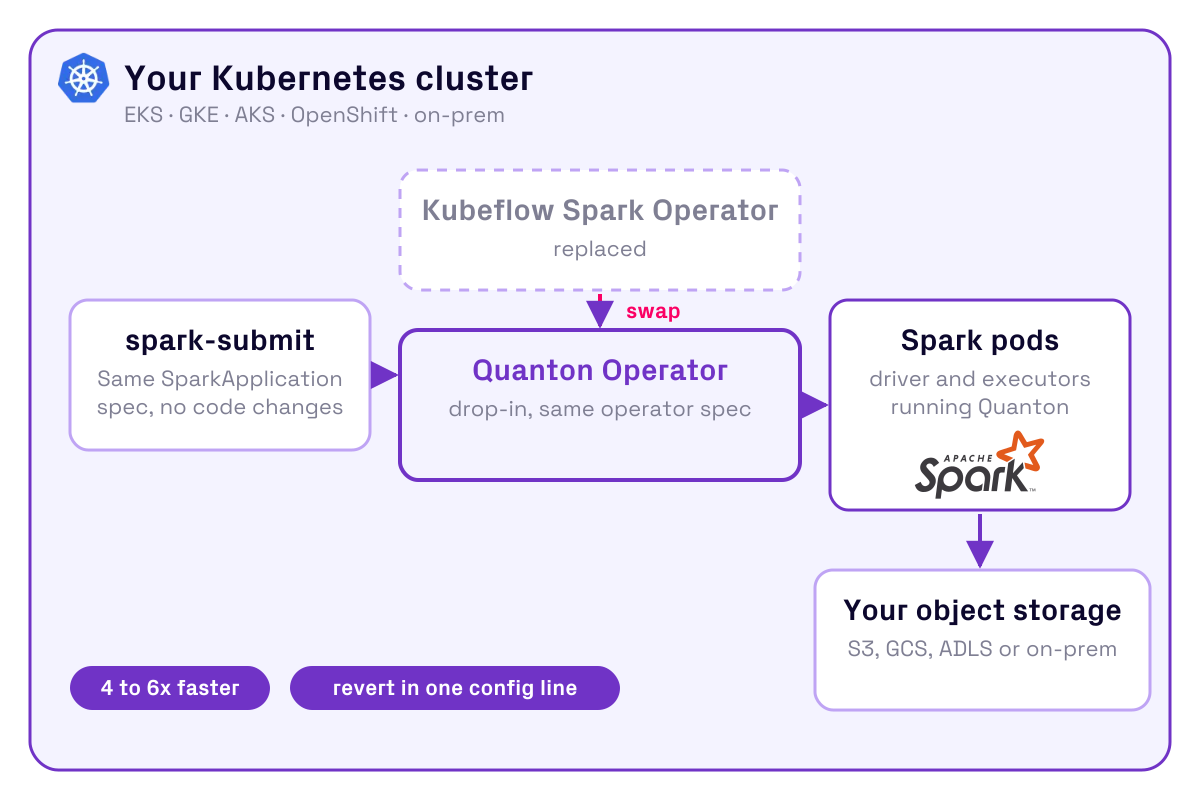
Photon runs only on Databricks compute. The Quanton Kubernetes Operator matches the Kubeflow Spark Operator spec and deploys driver and executor pods with Quanton instead of open-source Spark: 4x faster merges, 6x faster on TPC-DS, same spark-submit, your existing EKS, GKE, AKS or on-prem cluster. Reverting is one config line.
Go deeper on the open alternative
Blog
Databricks Iceberg support has a catch. It's called Unity Catalog.
Read article
Blog
Introducing Onehouse AI Gateway: routing without chains and tolls
Read article
Blog
Introducing the Quanton Kubernetes Operator for Apache Spark™
Read article
Keep your data. Lose the Photon tax.
get started today