Talk with our engineers by joining the new Onehouse community Slack!
Move to Open Table Formats
Snowflake's closed data format is dead.
Even Snowflake realizes the future is open formats. The modern way to run it: one engine on Iceberg tables in your own buckets, ingested once, transformed with real Apache Spark. Snowflake reads them. So can everything else.
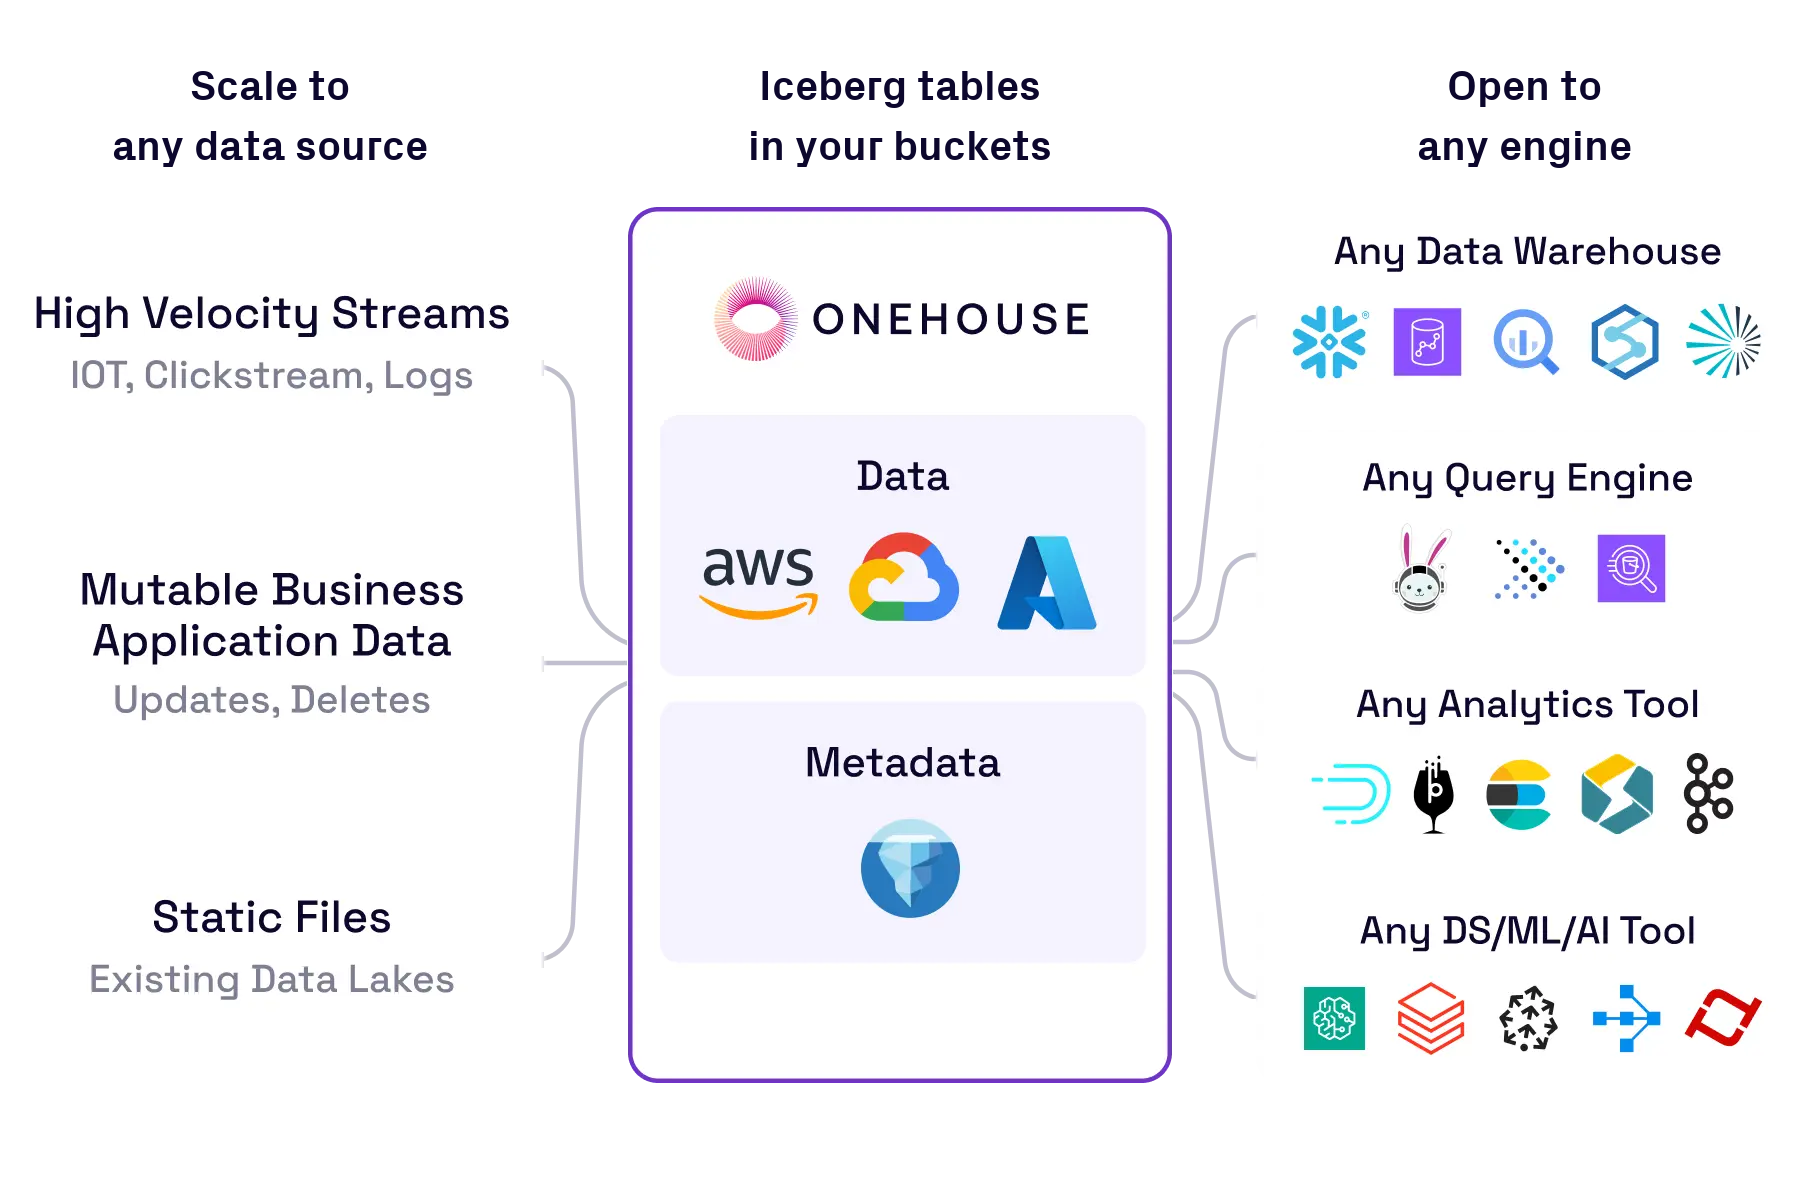
Ingest once. Query from Snowflake, and from everything else.
- Not locked in to one platform: OpenFlow feeds Snowflake only. OneFlow lands Iceberg in your buckets, synced to Horizon and Unity with grants via OneSync. Adding Spark, Trino or Ray is a catalog registration, not a migration.
- Built for CDC at scale: Record-level indexing and merge-on-read keep update-heavy Postgres, MySQL and Kafka streams landing as fresh, queryable Iceberg. When a second engine shows up, there is nothing to re-ingest.
- Runs in your account: OneFlow deploys into your AWS, GCP or Azure account. Iceberg lands in your bucket under your KMS keys and IAM; the control plane sees metadata, never rows. Delete the deployment and Snowflake still reads the tables.
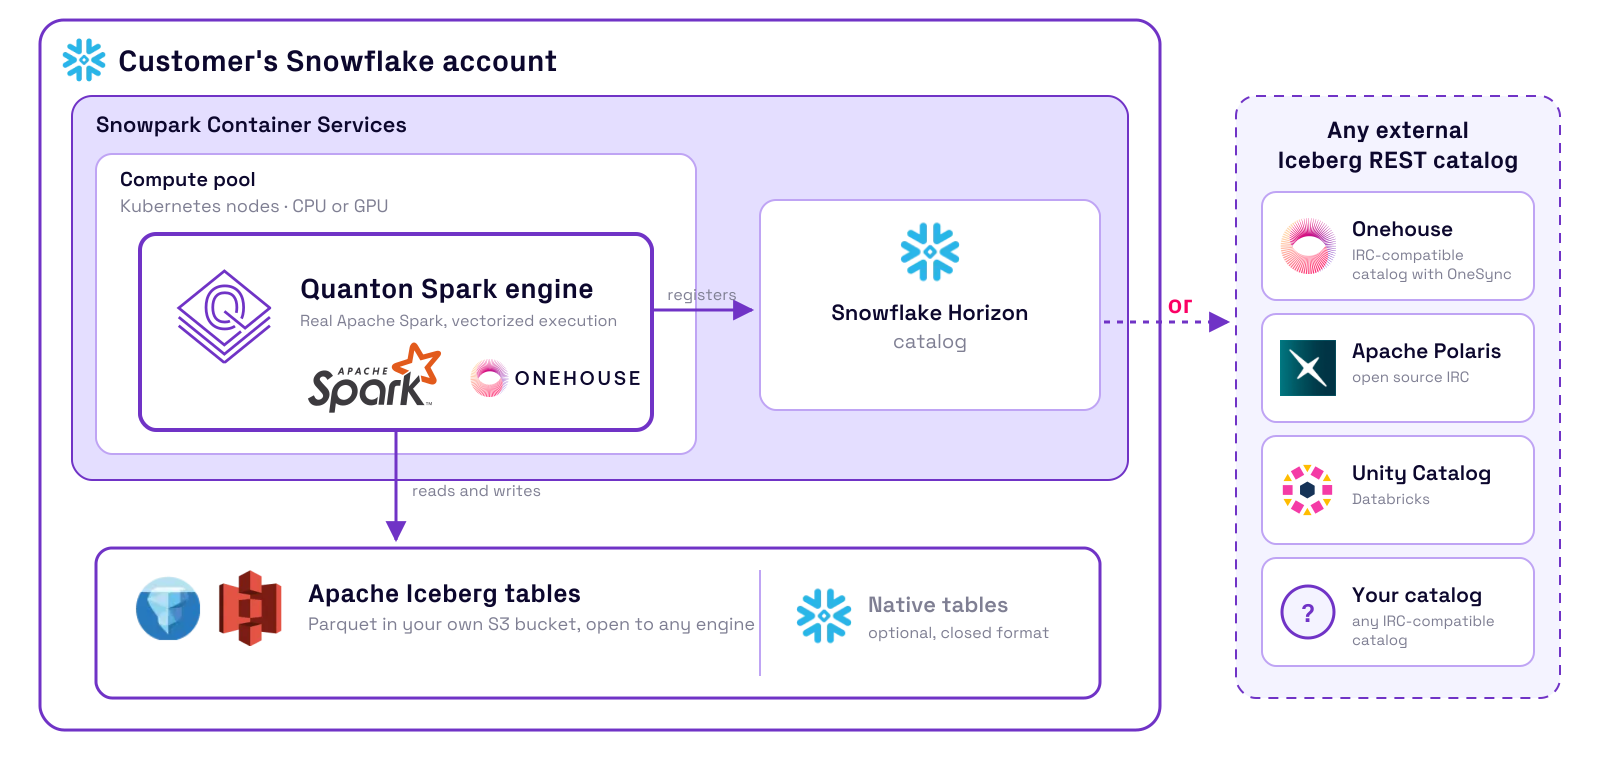
Run real Apache Spark inside Snowflake. Burn 63% fewer credits.
- Real Spark, not Snowpark: Quanton runs on Snowpark Container Services as actual Apache Spark: same DataFrame API, same SQL, same spark-submit, native Iceberg. Your jobs run unchanged.
- 63% fewer credits: 1TB TPC-DS on Quanton burns 63% fewer Snowflake credits than a Gen2 Large warehouse. Same credit bucket, no second vendor contract.
- Nothing leaves your account: PrivateLink, audit logging and RBAC apply to SPCS as they do to warehouses. Deploy from Snowsight SQL worksheets. Step-by-step guide.
| Capability | Snowpark | Apache Spark |
|---|---|---|
| DataFrame APIs | ✓ | ✓ |
| Spark SQL | ✓ | ✓ |
| RDD support | ✗ | ✓ |
| Structured Streaming | ✗ | ✓ |
| SparkML, MLlib | ✗ | ✓ |
| Language support | ✗Python only; Java/Scala in preview | ✓All Spark APIs |
| Where it runs | Premium Snowflake warehouse | Snowflake SPCS containers63% fewer credits |
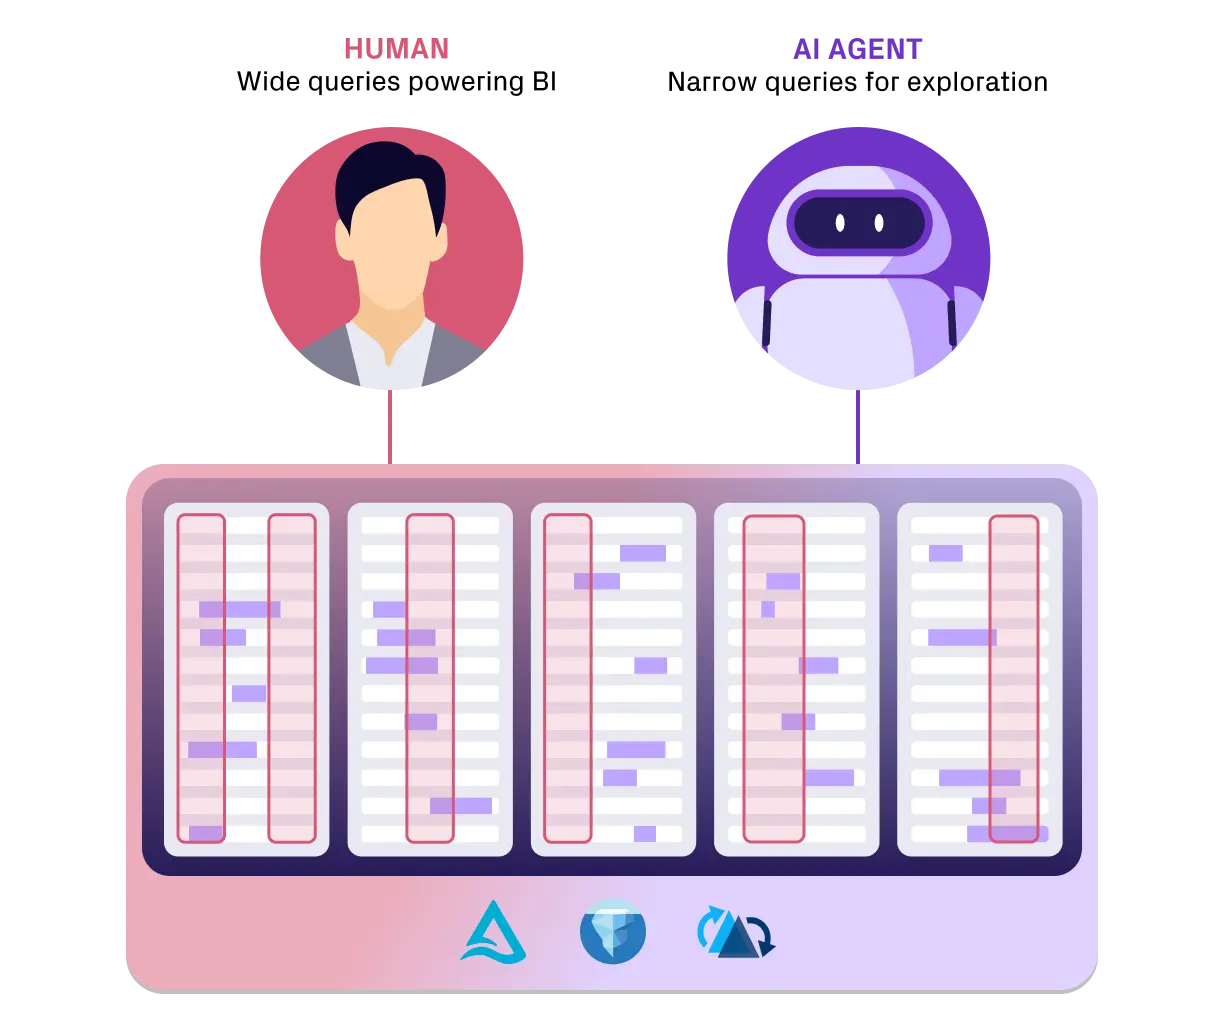
Agent and ad hoc queries burn a hole in a Snowflake budget. Lakegres is built for them.
- Agents do not query like analysts: One prompt becomes chains of point lookups, high-cardinality filters and six-month scans, in parallel, at hundreds of QPS. On Snowflake that is a warehouse kept running and sized for the spike, billed by the second.
- One endpoint, both query shapes: Lakegres serves narrow queries from record-level indexes in milliseconds (95% lower latency on 1TB TPC-DS point lookups) and wide scans through columnar caching and Quanton. Same Iceberg tables, no warehouse copy.
- Elastic on your own compute: Postgres wire protocol, so any client, BI tool or agent framework connects as-is. Scales up for the burst on your cloud at your rates, back down when the agent goes quiet.
Run Snowflake and Databricks on one copy of data. Peacefully.
OneSync Permissions
Define grants once; OneSync translates them between Snowflake Horizon and Databricks Unity Catalog, both ways, down to column and row level. Lake Formation and OneLake too.
One copy, every catalog
Each table registers with Open Catalog, Horizon, Unity and Glue as it lands. One pipeline and one bucket for the roughly 45% of teams running both Snowflake and Databricks.
Incremental processing
Downstream tables update from the diff, not a full recompute. Fresh gold tables in Snowflake without a catch-up warehouse.
Automated Iceberg table management
Compaction, clustering, snapshot expiry and schema evolution run in the background. Tables stay fast in Snowflake with no maintenance job to own.
Iceberg first, any format on request
Iceberg by default. Delta on request through Apache XTable™, with no second copy.
Moving the largest MERGE INTO workloads from Snowflake to open table formats on Spark cut compute from $1M to $300K a year, about 70%. Snowflake still queries the result.
NOTION’S JOURNEY
Optimize Your Snowflake Environment with Onehouse
Data sheet
Onehouse Iceberg for Snowflake
Download now
Blog
Real Apache Spark. Inside Snowflake. Quanton on Snowpark Container Services
read now
webinar
Iceberg for Snowflake: Implementing the fastest, most open data lakehouse for Snowflake ETL/ELT
watch now
Keep Snowflake. Lose the lock-in. Cut ETL cost by up to 75%.
let's talk