Talk with our engineers by joining the new Onehouse community Slack!
The concept of partitioning data has been long tied to enhancing query performance. Even though it sounds simple, it’s a nuanced technique and ill-designed partitioning schemes can also adversely impact query performance. I have been interacting with users in the Apache Hudi™ community on a daily basis for the past 3 years or so and have had the opportunity to witness both good and not-so-good approaches to data partitioning. In this blog, we discuss how different databases have approached data partitioning and how it has evolved on the data lake. We then present the most common pitfalls to be aware of based on such observations, aided by micro-benchmarks.
What is data partitioning?
- Improved scalability: Partitioning enables horizontal scalability by distributing data across multiple nodes. Additional partitions can be easily added to scale the systems to growing volumes if needed.
- Increased availability: By distributing the data to multiple nodes, the failure of one node does not lead to the entire database being unavailable. Rather only the affected partition may be unavailable.
- Better performance: Query execution can leverage parallelizing operations across partitions leading to faster response times, as well as often reducing overhead by not keeping metadata for irrelevant partitions in memory.
- Easier manageability and life cycle management: Partitioning can help isolate data that is frequently accessed (hot data) or modified, reducing contention and improving the overall system performance. As data becomes hot or cold, they can be moved to separate partitions or even archived, freeing up resources and improving overall efficiency. Further, background processes can be run on individual partitions instead of the entire database.
Data partitioning in Data Warehouses
Much of the database systems and early warehousing systems emphasize horizontal partitioning. This involves both data distribution techniques (also sometimes referred to as sharding) for better load balancing, throughput, and resource utilization of the cluster nodes and also data grouping techniques (referred to as partitioning) within every cluster node to prune the query space to selected subsets of data for improving query performances. Traditional data warehousing systems like Vertica and Teradata follow Massively Parallel Processing (MPP) architecture, where data is stored on local disks. While adding new nodes to scale the cluster, they use horizontal partitioning to distribute the data and strive to achieve even distribution of records across nodes to ensure multiple nodes take part in the query execution in parallel and maximize throughput. Most times hashing on the primary key column is preferred for data distribution since that guarantees uniform distribution and sometimes even a round-robin is used. This uniform distribution helps avoid data skews and equally distributes load to nodes in the cluster for better resource utilization. Within each individual node (physical database node or a virtual processor within a physical node), further, the data is partitioned based on a table column(s) to leverage parallel distributed computing to enhance query performance. Further, these systems optionally provide vertical partitioning based on columns within individual partitions to further enhance query performance for fetching only those selected columns involved in the query.
Cloud based data warehousing solutions like Redshift, Bigquery, and Snowflake all take slightly different approaches towards data partitioning and data layout (using sorting techniques). Redshift distributes data among the cluster nodes based on some distribution style like round-robin or based on a column value, etc. Even though this is similar to Vertica or Teradata, Redshift does not require partitioning within an individual cluster node. Rather, it depends on sorting techniques to limit the search space for range predicates in the query. Bigquery, uses partitioning to segment the table based on either the ingestion time or based on one column to aid pruning if a query uses a qualifying filter on the same column. If more granularity is required, clustering is recommended to accelerate query performances. Snowflake does not support traditional partitioning. Over concerns of data skew causing nonuniform partition sizes, Snowflake approaches this challenge with the concept of micro partitioning (that bounds the size of the partition - [50 - 500MB] rather than based on a column value) and clustering to sort underlying data. It manages metadata on each micro partition to be used for query pruning, in a scalable distributed key-value store.
Data Partitioning on the Data Lake
Data Lakes started out using predominantly used row-based formats such as Json, Avro for storing data. As late as 2015 when I left Linkedin most of its data was still in the Apache Avro format. Data partitioning was very simply organizing files into folders on distributed file systems like HDFS or cloud storage, based on a column (most commonly a date or time field in the dataset). In terms of query performance, this partitioning helped cut down the amount of data read from storage by only reading relevant folders/partitions based on query predicates. Since row-based file formats had to be read fully to process queries, data partitioning was the only tool in hand to improve query performance, resulting in users adopting complex partition evolution strategies (e.g starting with hourly partitions for recent data, then rewrite into daily partitions) or having too fine-grained partition columns (e.g partitioning on date and a sales region, to ensure critical overnight reports complete in time).
With the explosion of analytical needs in the last decade and evolution of query engines like Apache Spark™ and Presto, there has been a significant shift towards column-based file formats such as Apache Parquet and Apache Orc that provide other means to accelerate query performance, much like approaches we saw employed on Cloud data warehouses. Data is still horizontally partitioned for parallelizing operations, but also vertically partitioned using columnar storage formats to further improve query response times. Users are able to sort data and efficiently skip data files and even pages that are irrelevant to the queries, making some of the traditional approaches to data partitioning on the data lake, merely vices that we need to grow out of.
Vice 1: Partitioning does not match query shapes
Most query engines leverage partition pruning techniques to limit the data search to only those relevant partitions matching conditions specified in the query instead of processing all the partitions. These are achieved via filters and predicate push-downs during query analysis and planning phases. Query engines depend on such techniques to devise an optimal plan to execute the query instead of having to scan the entire table data. Partition-pruned executions can be orders of magnitude faster than executing the same query on a non-partitioned table with the same columns and data definitions. The same adverse effect can also be observed with tables partitioned differently than the actual query shapes.
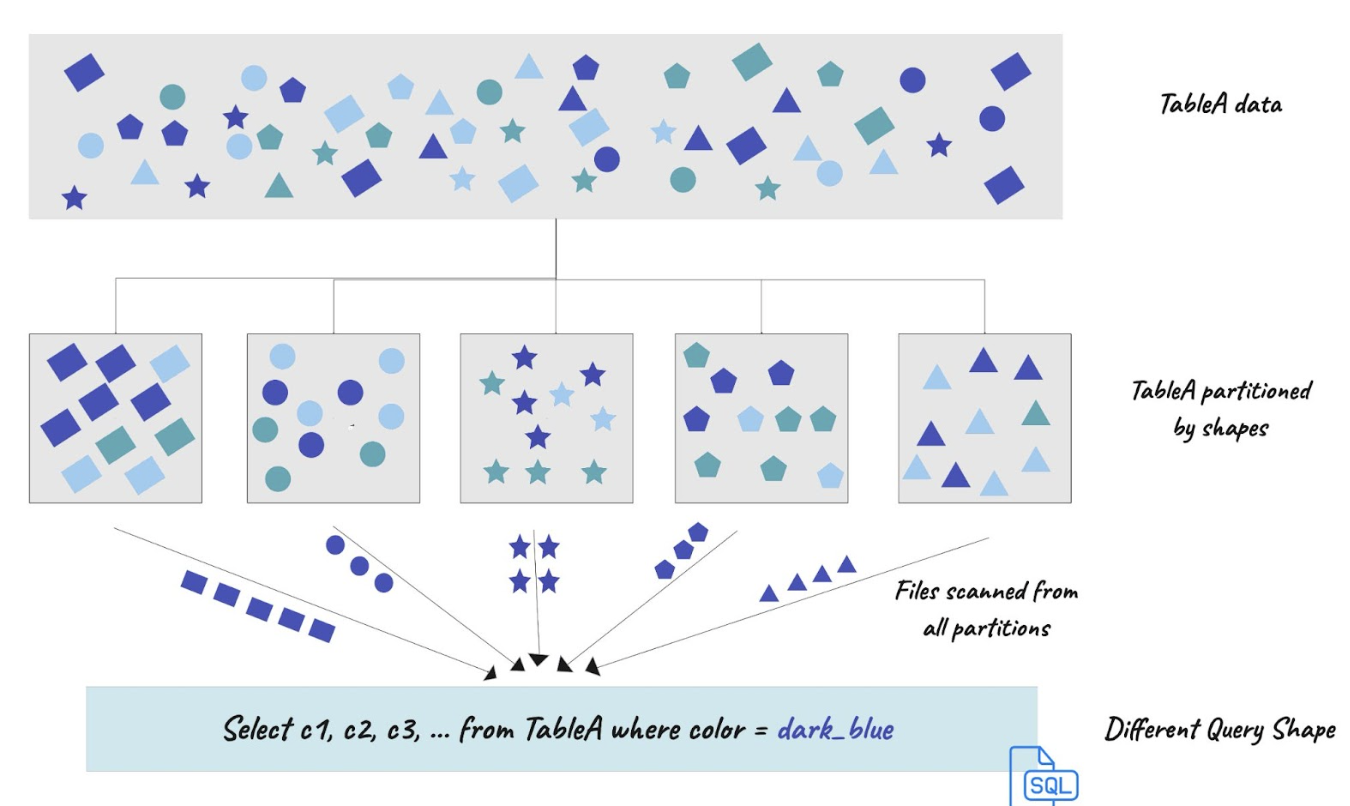
To illustrate this, we experimented with a simple query on the Amazon customer reviews dataset. This public dataset has over 130+ million individual customer reviews across different product categories between 1995 and 2015. We established two tables based on this dataset - one partitioned by product_category and the other partitioned by review_date and observed how the same query performed.
Query used for this experiment:
spark.sql("select marketplace, product_id, count(*),
          avg(star_rating) from <TABLE> where product_category = 'Books'
          group by 1,2 having avg(star_rating) >= 4 order by 3 desc,4 desc").show(20)
hudi-spark-sql-query.scala — hosted with ❤ by GitHub
This query lists the best books in each marketplace based on the total number of reviews and average star_rating >= 4. Below are the snippets of the final query execution plan collected from Spark UI SQL tab after executing the same query on both these tables on local disk.
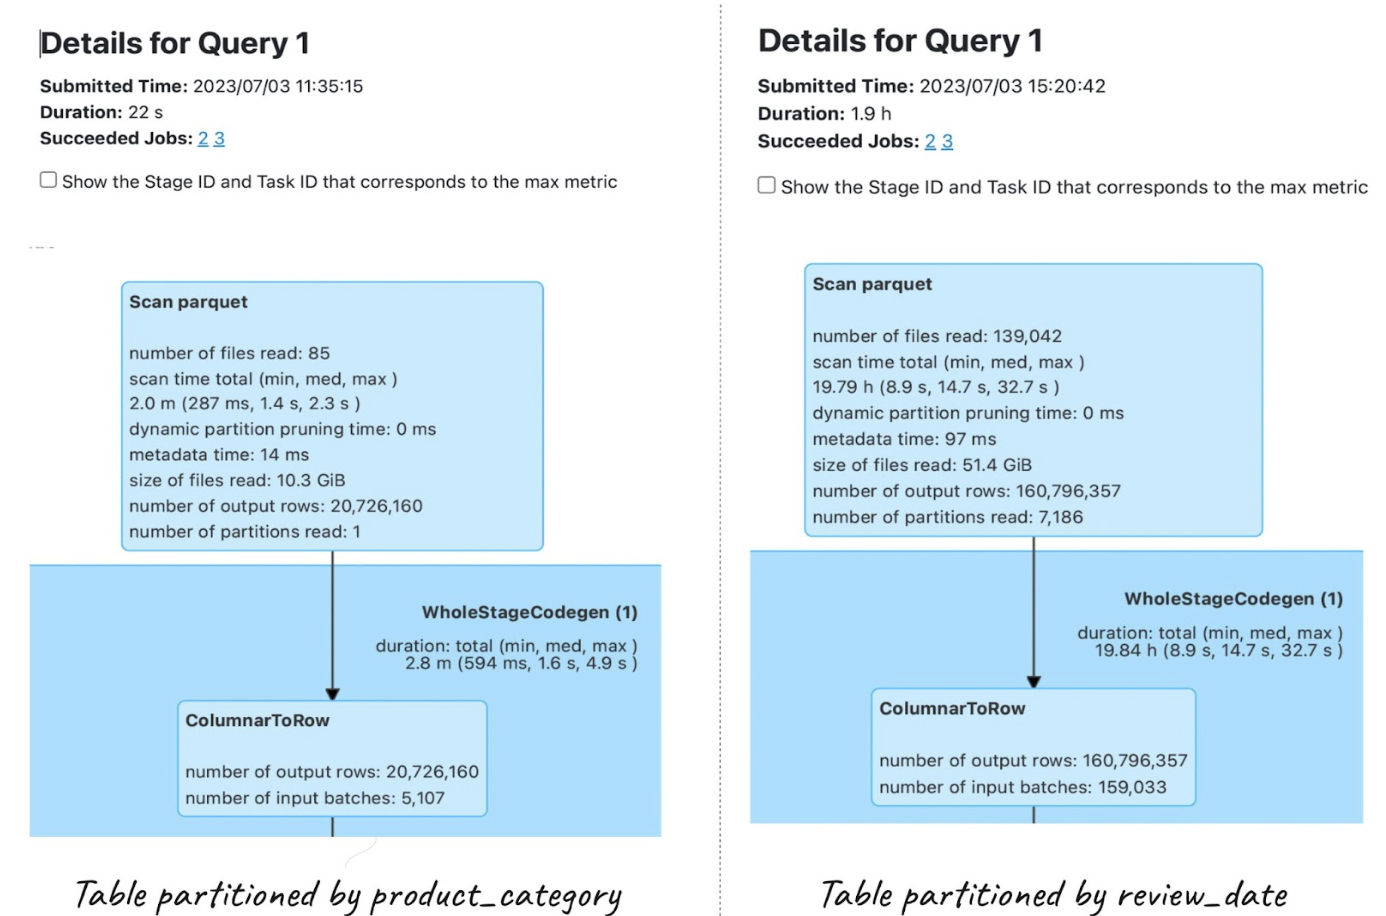
The query that ran on product_category based partitioning took just 22 seconds whereas the full table scan on review_date based partitioning took almost 2 hours. The total number of partitions on the first table is 43 and since this query is based on a specific product - Books, we see the partition pruning kicking in to reduce the search to 1 as indicated by “number of partitions read”. Whereas the total number of partitions in the second table partitioned by review_date is 7186 ( roughly along the number - 20 years * 365 days). Since each of those partitions can have a review on a book, this query has to scan all the partitions and all the files (139042 files read in total). As seen here, choosing the right high-level partitioning field is vital in pruning the query search space. Mismatch in data partitioning schemes and query shapes can lead to significant query performance degradation.
Vice 2: Partitioning is too granular
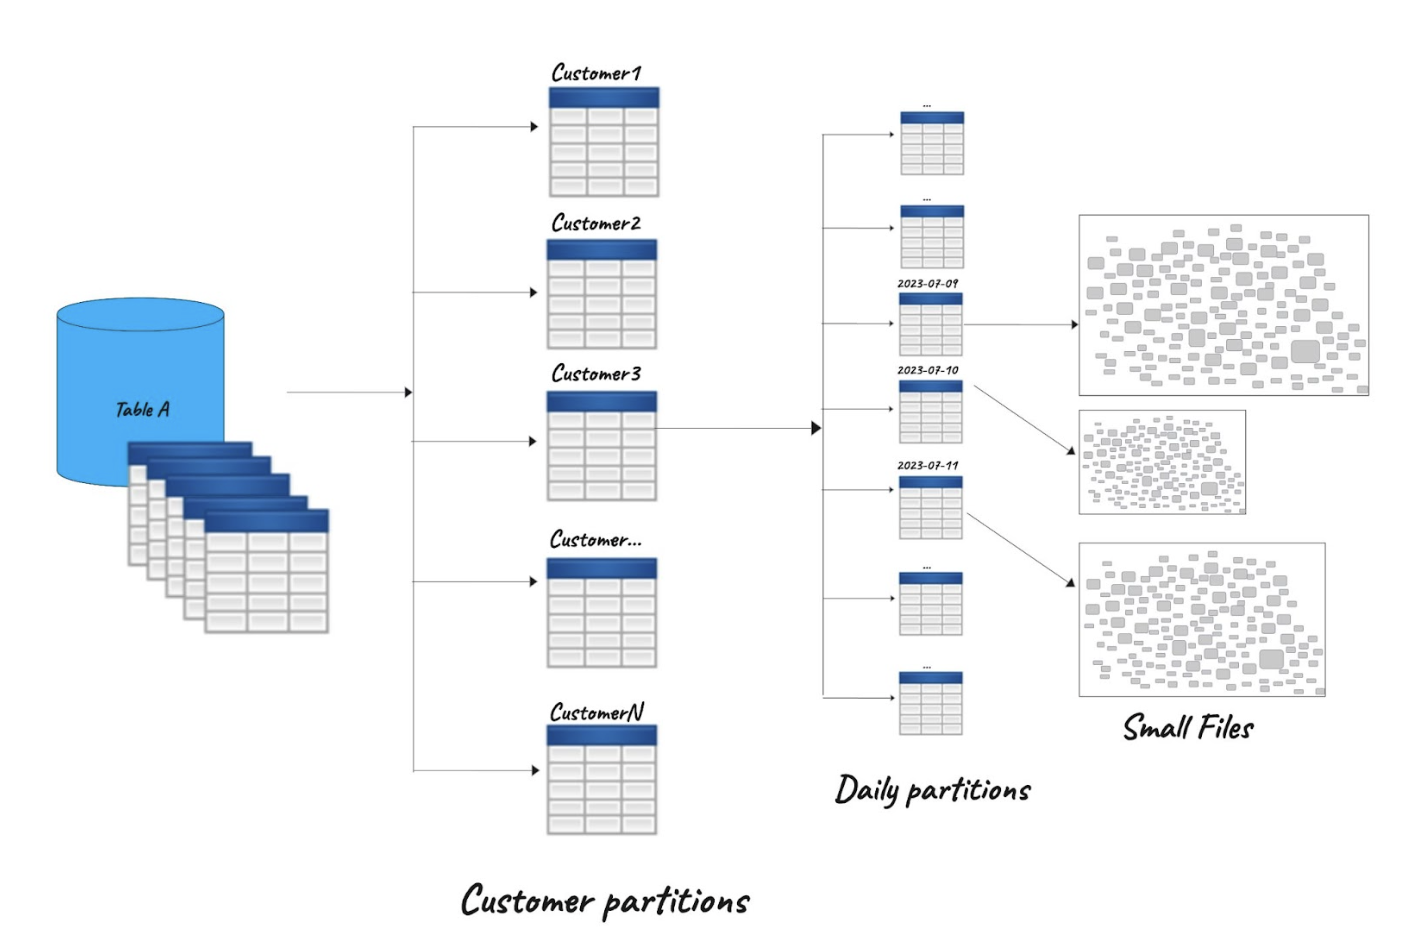
Consider a large SaaS enterprise X with data across its 150 customers that wants to retain at least 5 years of data and starts with a partitioning scheme of
spark.sql("select marketplace, product_id, count(*),
         avg(star_rating) from <TABLE> where product_category = 'Books'
          group by 1,2 having avg(star_rating) >= 4 order by 3 desc,4 desc").show(20)
hudi-spark-sql-query-2.scala — hosted with ❤ by GitHub
Alternatively, if company X had chosen a coarser
In the example above, we only assumed a single file per day. In reality, a single day’s partition tends to have multiple data files depending on factors such as: the frequency of the ingestion, sources of ingestion or optimizing techniques employed such as repartitioning, small file handling, etc. Additionally, uniform data distribution across naturally partitioned datasets is too perfect to be true. Partitions can be skewed due to factors like bursty traffic, weekends traffic patterns, customer’s data size, etc.
Having granular partitions in these scenarios, fragments the data creating tons of small files and leads to dramatic query performance degradation and cloud spend wastage. To illustrate this better, we established different tables with the same partitioning scheme but varied data file sizes in each of them. Then we assessed the performance of the same query on all these different tables.
Query used for this experiment:
spark.sql("select marketplace, product_id, count(*),
          avg(star_rating) from <TABLE> where product_category = 'Books'
          group by 1,2 having avg(star_rating) >= 4 order by 3 desc,4 desc").show(20)
query3.sql — hosted with ❤ by GitHub
We used the same query as earlier - that lists the best books in each marketplace based on the total number of reviews and average star_rating >= 4.
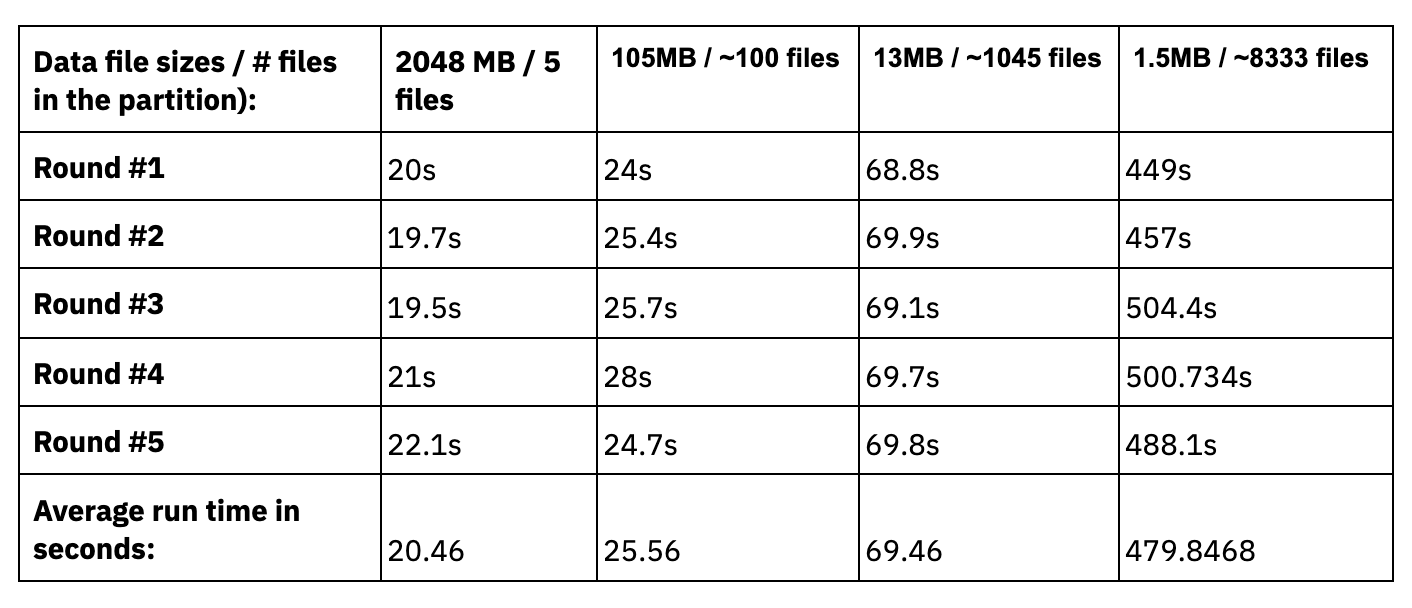
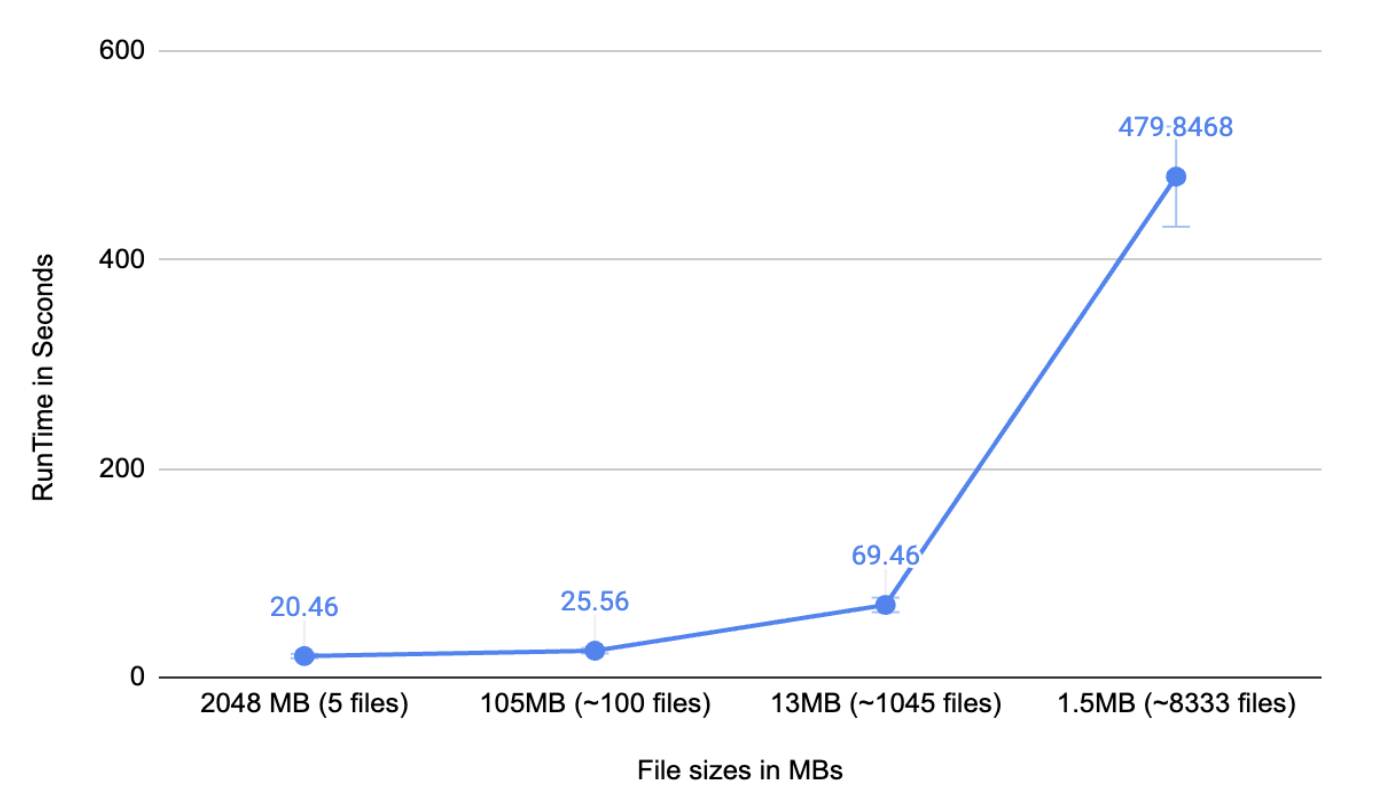
The execution time increases to ~8 mins if the data files are merely 1.5 MB in size, while there is no noticeable difference in performance from 2GB to 105MB. This underscores the need for maintaining big enough file sizes, to offset the additional metadata overheads associated with query processing. Drawing from the example before, as company X goes through rapid growth, following the_
Vice 3: Partitioning is not implemented uniformly
As called out before, one of the last relics of the early data lake design is evolving partitioning from finer-grained to coarse-grained, as the data gets colder. Borrowing from the same example above, company X might want to start with a partitioning scheme
Modern data lake storage systems support the ability to atomically commit data that is completely decoupled and independent of data partitioning schemes, and even support near real-time write speeds. Furthermore, the notion of declaring partitions immutable with a _SUCEESS file is fundamentally unsuited when dealing with mutable and out-of-order data streams, that almost every company is embracing today. Complex partition evolution makes for unpredictable query performance. In our example, a query spanning the last 60 days would have to process a mix of 60 MB files for 1 month, 3 MB files for 29 days and even smaller files at hourly granularity for the current day. This introduces stragglers/data skews into query processing, making it very difficult for data consumers to understand expected performance and data platform providers to meet SLAs, plan capacity or optimize costs.
An important consideration that is often overlooked when choosing such schemes, is the amount of query volume that is exposed to small files and unoptimized data partitions during a day or the course of the month before rewriting into bigger files/partitions can be done. Data lakes typically have very high read:write ratios, with large enterprises routinely running millions of queries on the same dataset each day, while writes to tables happen only a few hundred times a day, even for near real-time data pipelines committing data every few minutes. Using the numbers we produced earlier on how small files affect query performance, we need to spend about 19x more time processing queries with small 3MB files, compared to having well-sized 60 MB files in the partitions. Table below models the costs per day, given the query volume.
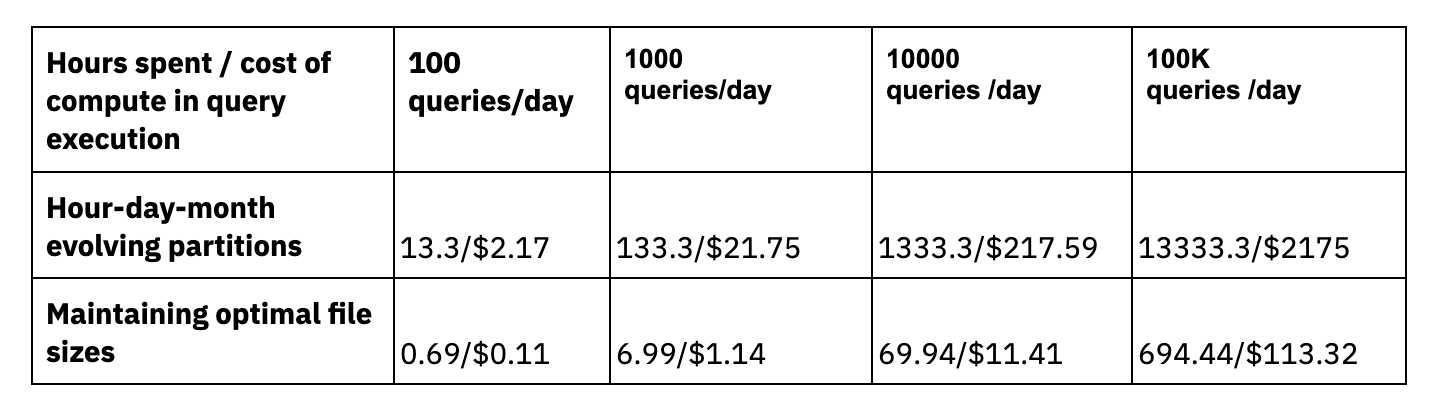
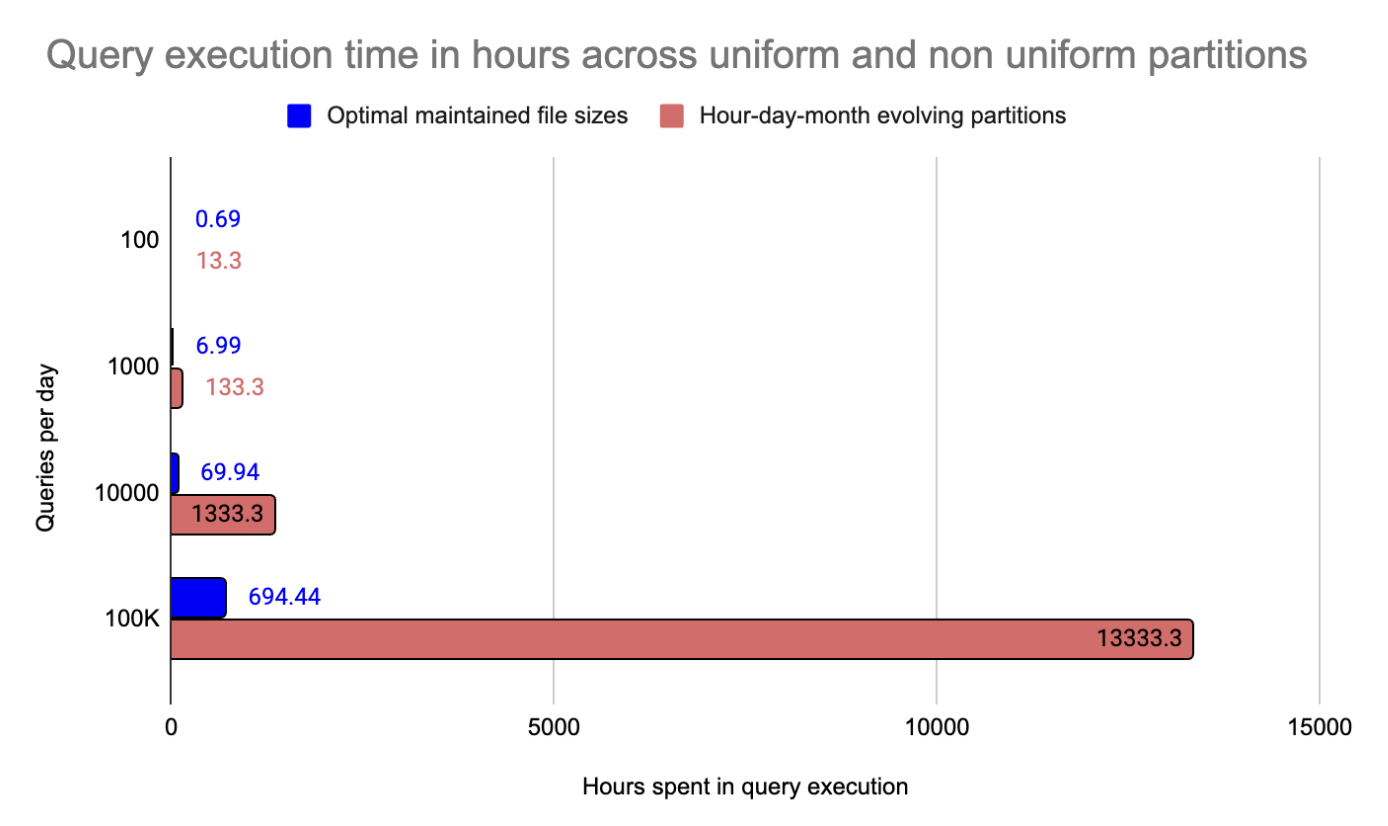
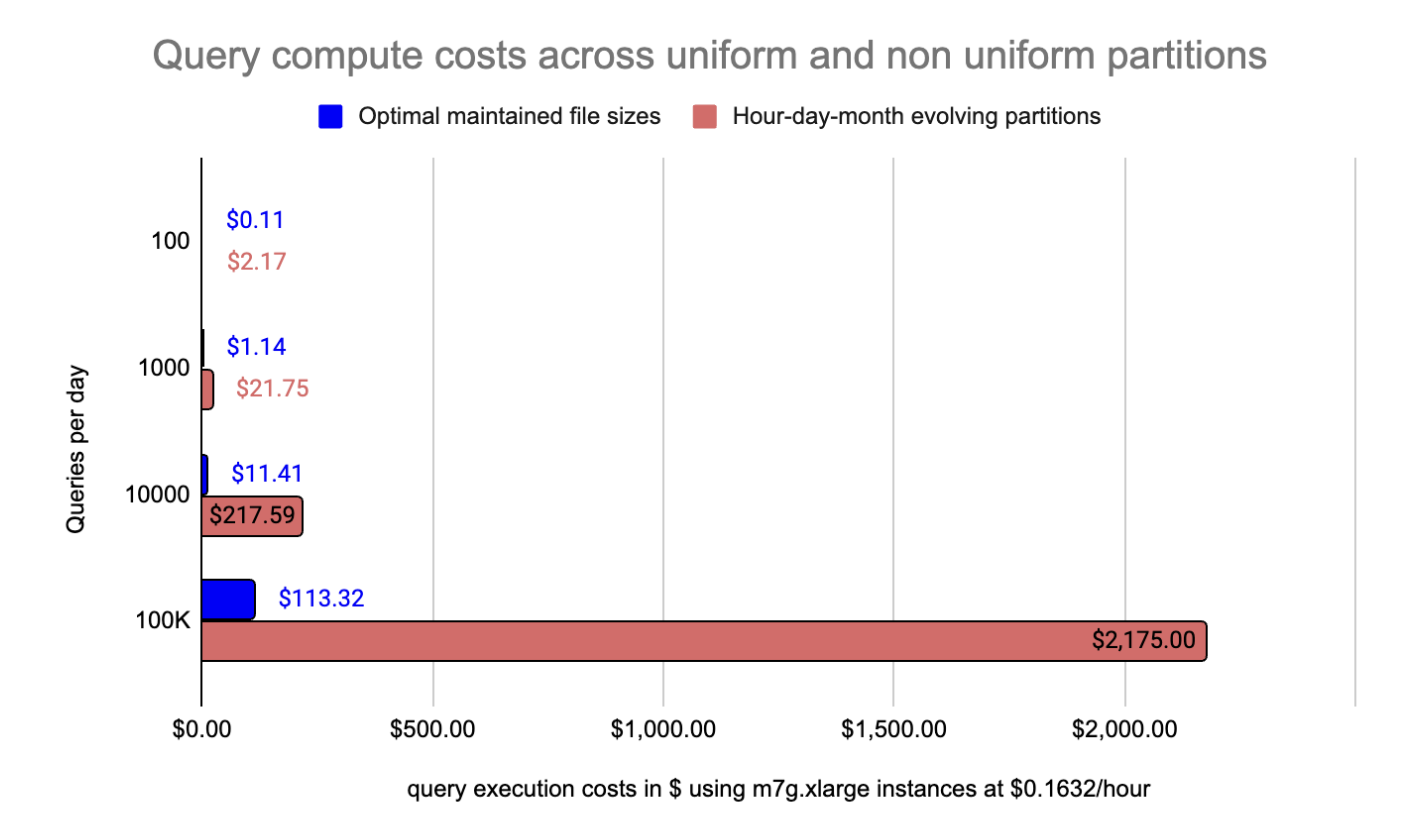
Even though we have used a single query to extrapolate here, we are confident that similar dramatic cost savings/performance gains will be observed with complex queries as well, since these differences are just resulting from how efficiently data can be read out of a single table. It’s worth noting that there are costs to maintaining optimal file sizes while meeting data freshness SLAs, but they can be easily paid for several times over by query side cost savings shown above.
Conclusion
In this blog, we reviewed the underlying principles of data partitioning, how it’s implemented across various data warehouses and a deep dive into how it manifests itself on the data lakehouse. With the advent of new storage technologies in the data lake space over the past years, it’s time to break some bad habits around data partitioning. Ultimately, choosing the right granularity and keeping consistent data partitioning across datasets is critical to achieving predictable performance on the data lake. We hope that this blog helps users make better decisions around data partitioning and we hope to share recipes for avoiding these pitfalls in a future blog. In the meantime, we love to hear your thoughts. Please engage with us in the Hudi community and join our Slack!